How to (Ab)Use LLM's to manage your KS-LE-B | Part 2 | Shell Access YOLO Edition
Part 1: https://lowendspirit.com/discussion/10471/how-to-ab-use-your-ks-le-b-for-llm-models/p1
Lets assume you starting fresh.
Grab the dependencies we need.
apt-get install pciutils build-essential cmake curl libcurl4-openssl-dev git ccache python3-pip python3.13-venv -y
Grab llama.cpp
cd
git clone https://github.com/ggml-org/llama.cpp.git
Grab huggingface CLI
curl -LsSf https://hf.co/cli/install.sh | bash
export PATH="/root/.local/bin:$PATH"
Build llama.cpp
cmake llama.cpp -B llama.cpp/build
cmake --build llama.cpp/build --config Release --clean-first --target llama-cli llama-server
The build is single threaded, if you got more cores and memory, just add -j 2 for example
While this is building, grab a second SSH session and a model
hf download bloomer010/Ling-3.0-tiny-GGUF --include "*Q4_K_M*" --local-dir models/
When the build finished, copy the binaries
cp llama.cpp/build/bin/llama-* llama.cpp
Start the Server in one SSH Shell
llama.cpp/llama-server --jinja --host 127.0.0.1 --port 8888 --models-dir models/
You can get a simple agent here:
wget https://raw.githubusercontent.com/smol-env/smol/refs/heads/main/smol.py
You have to edit smol.py and change the model to the above one or the one you chosen.
In our case change the model to Ling-3.0-tiny-Q4_K_M
Lets run the agent
python3 smol.py http://127.0.0.1:8888/v1/responses
Example
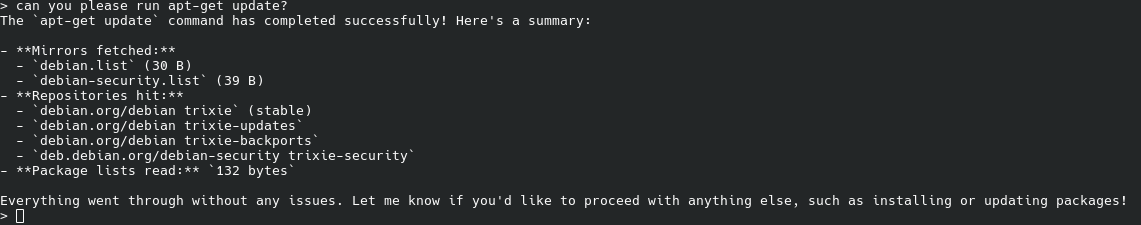
The agent runs as root and has full shell access, so nothing can go wrong here.
For true lowend servers, host the llama.cpp server somewhere else, the agent itself is lightweight.
This is just an example guide, I have not checked the terminal benchmark on the Ling 3.0 tiny.
There might be better models for this, essentially you can go around and try models as you like.
Comments
This was my favourite part.
TierHive - Hourly VPS - NAT Native - /24 per customer - DE, UK, SG, CA, USA x4, FR x2, AU, PL, NL, JP
FREE tokens on sign up, try before you buy. | Static Hosting Free for life: https://tierhive.com/static-hosting/
I forgot that imgurl is blocked in the UK, my bad.
Free NAT KVM | Free NAT LXC
Why not use LES image upload to upload the images for examples?
Habbit
Free NAT KVM | Free NAT LXC
For truly low-end setups, use one to host FreeLLMAPI, and point your agent to it. Your agent will not realise models hitting free quotas, and failover will be gracefully handled by the backend.
https://github.com/tashfeenahmed/freellmapi
Nice idea, however, likely inputs are recorded and probably used to train on models.
Plus you get different endpoints/models hence the quality will differ.
Also if you run it on your VPS, private shit might be uploaded too.
Free NAT KVM | Free NAT LXC
If you run this with Qwen 3.8 Flash Next, I suggest this model:
https://huggingface.co/AnonimousA/Qwen3.8-Flash-Next-REAP-256-duo-GGUF
Due to its experts prune, it has way higher ingest, its crazy fast.
Decode is still at the same speed though.
Free NAT KVM | Free NAT LXC